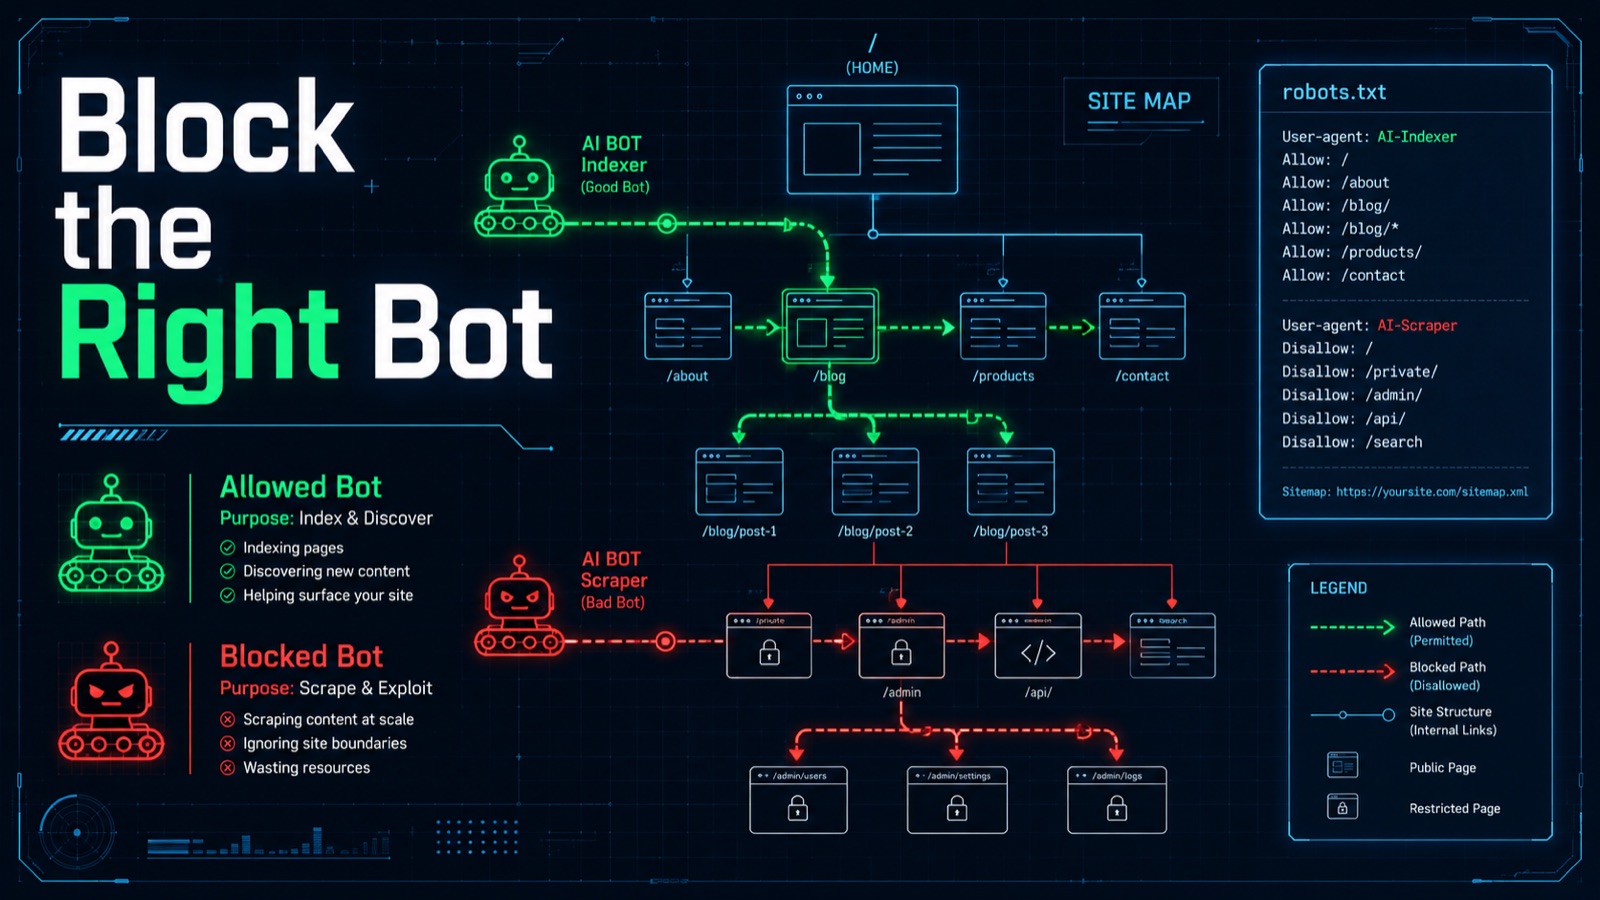
GPTBot and OAI SearchBot are separate OpenAI crawlers with different purposes. Treating every OpenAI user agent as the same thing can lead a company to block search visibility when it only intended to limit training related crawling, or to allow crawling it thought it had restricted.
That makes robots.txt a marketing decision as well as a technical one. The right configuration depends on whether the goal is discoverability, model training control, content protection, or a combination of those objectives.
What is the difference between GPTBot and OAI SearchBot?
OpenAI documents OAI SearchBot as the crawler used to help surface websites in ChatGPT search. GPTBot is documented separately in relation to crawling that may be used to improve generative AI models.
Those jobs are not interchangeable. A site may reasonably want to allow search discovery while taking a different position on training related crawling.
OpenAI's publisher and developer guidance says sites that want content included in ChatGPT search summaries and snippets should make sure they are not blocking OAI SearchBot.
Why does blocking the wrong crawler matter?
Because the technical rule can create the opposite business outcome from the one intended. A marketing team might ask engineering to "block AI training" and end up with a broad rule that also blocks search discovery.
The reverse can happen too. A company may believe it blocked ChatGPT entirely while leaving the search crawler accessible.
The problem is usually language. "AI bot" sounds like one category, but different agents can perform different functions. Policy should be written around purpose rather than brand name alone.
Is robots.txt enough to control AI access?
No single robots.txt rule should be treated as a complete security boundary. robots.txt communicates crawler preferences to compliant automated agents, while access controls, authentication, CDN rules, firewalls, application permissions, and other infrastructure determine what a system can actually reach.
For public marketing content, robots.txt is still important because compliant search crawlers use it to understand allowed paths. For private or sensitive information, stronger technical controls are necessary.
That distinction matters because discoverability and security are different problems. Marketing wants selected public pages to be easy to retrieve. Security wants private resources to remain inaccessible regardless of crawler etiquette.
Who should own AI crawler policy?
Marketing, security, and engineering should share it. Each team owns a different part of the decision.
Marketing should define which public resources need discoverability. Security should define which information must remain protected or restricted. Engineering should implement the rules and verify the actual behavior through logs and infrastructure controls.
Companies working on AI visibility should include crawler configuration in the audit rather than assuming a content strategy can succeed independently of technical access.
What should a practical crawler review include?
Start with the intended outcome, then compare it with the actual configuration. Do not begin by copying a generic robots.txt block from another website.
Review:
- Which OpenAI and other AI crawlers are named in robots.txt.
- Which public sections are allowed or disallowed.
- Whether the CDN or WAF blocks crawlers independently of robots.txt.
- Whether important pages require authentication or fail for automated requests.
- Whether server logs confirm the crawler behavior the team expects.
The objective is not to allow everything. It is to make access deliberate.